
Cleaning Filler Words From Podcast Captions


Delete the filler that makes a caption look broken, repeated words, false starts, and stray "um"s stacked at the start of a line, and keep the filler that makes a person sound like a person. The fast move: do a caption-only cleanup that changes the text but not the audio, and only cut the audio itself when the filler leaves a real gap or stumble in the talking.
That one distinction, text-only edit versus audio cut, is where most people get this wrong. They either leave the captions verbatim and the clip reads like a court transcript, or they hack the audio to match every deletion and end up with a jumpy, robotic-sounding clip. You want neither. Below is the triage rule for which words to remove, and the matrix for when the caption edit has to follow the cut and when it must stay put.
Should you remove filler words from captions at all?
Yes, but selectively. Verbatim captions on a fast vertical clip read cluttered and slow the eye down, and most social video is watched on mute, so the captions are the clip. A line crowded with "um, like, you know" gives a muted reader nothing and steals attention from the actual point. Cut the noise, keep the human.
How muted is "most"? A widely repeated estimate puts around 85% of Facebook video viewed with the sound off (Digiday, 2016 publisher-reported data; treat it as directional, since it's a decade old and individual studies range from roughly 69% to 85%). The exact number doesn't matter for this decision, what matters is that a large share of your audience only ever reads the words.
But total removal is a mistake too. A clip where every speaker talks in clean, complete sentences reads as scripted, and scripted reads as an ad. The small hesitations are part of why people trust a conversation. The goal is not zero filler. It's removing the filler that distracts while keeping the filler that humanizes.
The triage rule: which words to actually cut
Run every filler word through three questions before you touch it. Most decisions resolve in seconds.
- Does the word carry meaning? "I mean" and "you know what I mean" sometimes do real work, they signal emphasis or a shift. A bare "um," "uh," or "er" never does. If it carries meaning, keep it.
- Does it clutter the line? Filler hurts most when it's stacked ("so, like, um, basically"), repeated ("the the the point is"), or sitting at the front of a caption where it's the first thing the eye lands on. If it clutters, delete it from the caption.
- Would cutting it break the audio? This only matters if you're also cutting the audio. If the word is buried inside a clean run of speech and removing the audio would leave a click or a swallowed syllable, leave the audio alone and edit the caption only.
The practical upshot: the large majority of "um"s and "uh"s are caption-only deletes. You change the text, the audio plays untouched, and the viewer watching on mute gets a clean line while the viewer with sound on hears a natural human. That mismatch is fine, captions have always condensed speech, and nobody expects a word-for-word transcript on a Reel.
Filler types, ranked by how much they hurt
Not every filler word costs the same on screen. A false start at the top of a caption is far worse than a single "like" in the middle of an otherwise strong line.
Work top-down. Kill the false starts and repeated words first, those are the ones that make a caption look like an uncorrected transcript. The "likes" and "you knows" at the bottom are judgment calls; leave a few in if the speaker's whole rhythm depends on them.
When to delete filler vs keep it for authenticity
Keep filler when it's load-bearing for personality, emotion, or pacing, a comedian's deliberate "uhhh" before a punchline, a guest's audible hesitation before an honest answer, a host's signature verbal habit. Delete it when it's mechanical noise that adds nothing but clutter: throat-clearing "ums," restarts, and repeated words. Authenticity lives in the hesitation that means something, not in every reflexive sound.
A useful test: read the caption line out loud without the filler word. If it loses its character or emotional beat, keep the word. If it just gets faster and clearer, cut it. A clip of someone choking up before they answer is stronger with the "I... I don't know if I can talk about this." A clip of someone explaining a concept is stronger without the three "ums" they used to find the next word.
There's one more honesty point worth stating: cleaning filler is not the same as changing meaning. Trim hesitation, never edit a sentence so the speaker appears to say something they didn't. Tightening "um, I think the data is, like, pretty clear" into "I think the data is pretty clear" is fair. Cutting "I think" so it reads "the data is pretty clear" is not, you just turned a hedge into a claim. Keep the qualifiers; cut the noise around them.
How caption edits should sync with the audio cut
This is the part nobody explains. There are two completely different operations, and the timing rules are opposite.
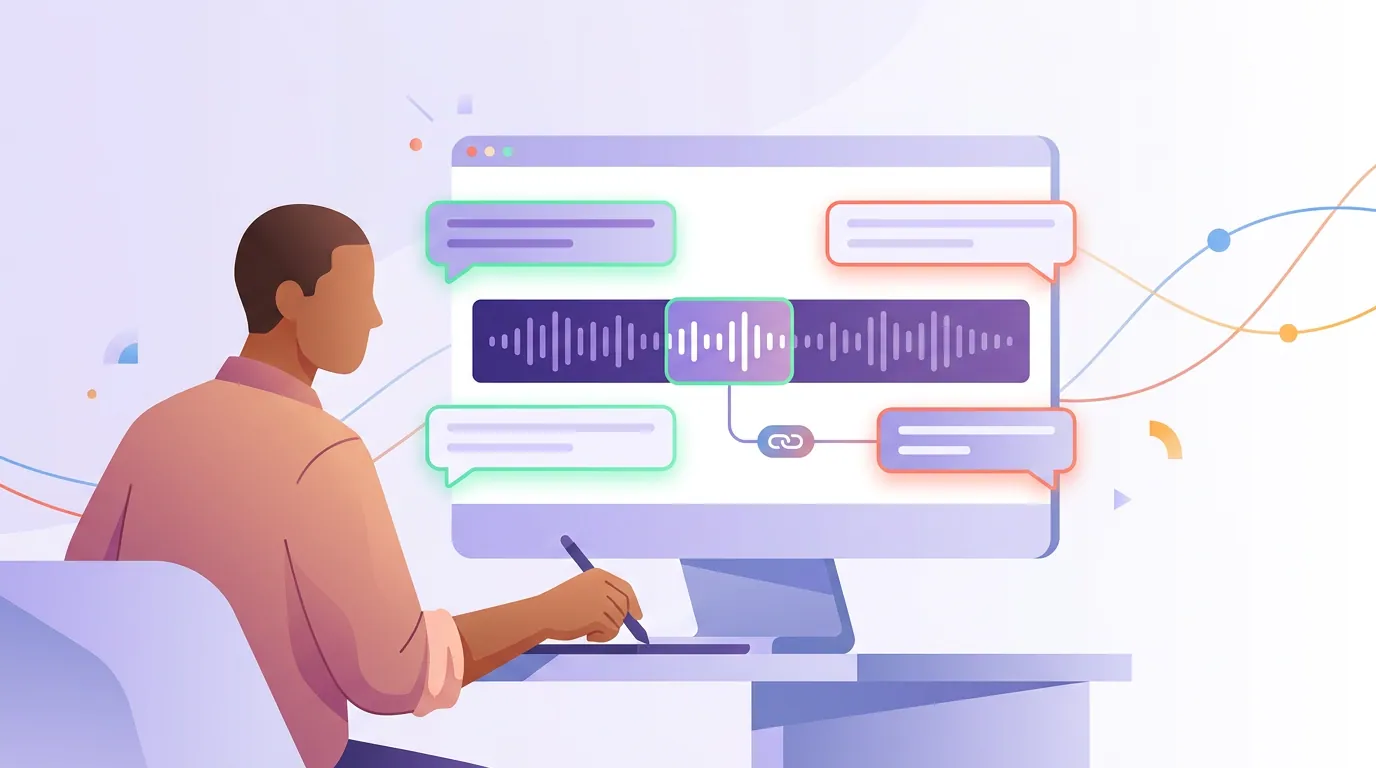
A caption-only edit changes the on-screen text while the audio plays untouched. The audio still contains the "um," but the caption skips it. Your only job is to make sure the cleaned caption still appears and disappears in roughly the right window so the words on screen line up with the words being spoken. You do not re-time anything else.
A cut-the-audio edit removes the word from the recording itself, the waveform gets shorter. Now every caption after that point shifts earlier, and if your tool doesn't re-sync automatically, your captions will drift out of step with the audio for the rest of the clip. This is the classic failure: someone deletes three "ums" from the audio, never re-syncs, and by the end of a 45-second clip the captions are a full word behind.
The rule that keeps you out of trouble: default to caption-only edits. They're free, they never desync, and they cover the large majority of filler. Reserve audio cuts for the few moments where the filler leaves a long dead pause or a genuinely awkward stumble that you can hear, and when you do cut the audio, use a tool that re-syncs the word-level caption timing automatically, or re-export the captions after the cut. If your tool ties captions to the transcript and the transcript to the waveform, this happens for you. If you're hand-timing an SRT, every audio cut is a manual re-sync, which is why hand-timing punishes audio edits. (More on the soft-file tradeoff in burned-in vs soft captions.)
Common mistakes
- Editing the audio when you only needed to edit the caption. Nine times out of ten, deleting the word from the caption and leaving the audio is the right call. It's faster, it never desyncs, and the muted majority gets a clean read.
- Stripping every filler word. A clip with zero hesitation sounds scripted. Keep the human ones. Run the read-aloud test before you delete.
- Cutting audio without re-syncing. The single most common reason captions drift on a finished clip. After any audio cut, confirm the captions still land on the right words for the rest of the clip, not just at the cut.
- Changing meaning while "cleaning." Removing hedges, qualifiers, or context to make a line punchier crosses from editing into misquoting. Trim noise, not nuance.
- Doing it line by line from the top. Search for the words instead. Most editors let you find every "um," "uh," and doubled word at once. Fixing by pattern is faster than reading every caption, the same targeted approach as a caption accuracy review.
Tools and where this fits
Most auto-caption tools transcribe verbatim by default, which means filler comes through exactly as spoken. A few, Descript's word-level transcript editing, and AI clippers that build captions from the transcript, let you delete a word from the text and choose whether it also cuts the audio. That choice is the whole game. Pick a workflow where the caption, the transcript, and the waveform stay linked, so a caption-only delete stays caption-only and an audio cut re-syncs everything downstream automatically.
In QuickReel, captions are generated from the transcript when you bring in an episode, so cleaning filler is a search-and-delete on the caption text, and audio cuts re-time the word-level captions for you. It's the same place you'd add captions to a podcast clip, pick a caption font, or decide auto vs manual captions. Whatever tool you use, the principle holds: clean the captions aggressively, cut the audio sparingly, and keep the filler that makes the speaker sound like themselves.
FAQ
Should I remove "um" and "uh" from podcast captions? Yes, in most cases. Bare "um" and "uh" carry no meaning and clutter the line for the muted majority who read captions instead of hearing them. Delete them from the caption text. You usually don't need to cut the audio too, a caption-only edit is faster and never desyncs.
Does deleting filler from captions change the audio? Not unless you tell it to. A caption-only edit removes the word from the on-screen text while the audio plays untouched, which is the right default. Cutting the audio is a separate, heavier operation that shortens the recording and forces every later caption to re-sync.
Is it dishonest to edit filler out of captions? No, as long as you only remove hesitation, not meaning. Captions have always condensed speech, and trimming "um, like" is standard. It becomes a problem only if you cut qualifiers or context so the speaker appears to say something they didn't.
Should I keep any filler words at all? Yes. Keep filler that's load-bearing for emotion, comedy, or a speaker's signature rhythm, the hesitation before an honest answer, the deliberate pause before a punchline. Use the read-aloud test: if the line loses its character without the word, keep it.
Why do my captions drift after I cut filler? Because you cut the audio without re-syncing. When you shorten the waveform, every caption after the cut needs to shift earlier. Tools that link captions to the transcript and waveform do this automatically; hand-timed SRT files need manual re-syncing after every audio edit.